
Managing the 10,000-finding surge: Operationalizing Wiz and Orca in the first 90 days
Wiz and Orca rollouts often surface 10,000+ findings in the first month. Here is how mid-market and enterprise teams navigate the gap between visibility and remediation capacity.
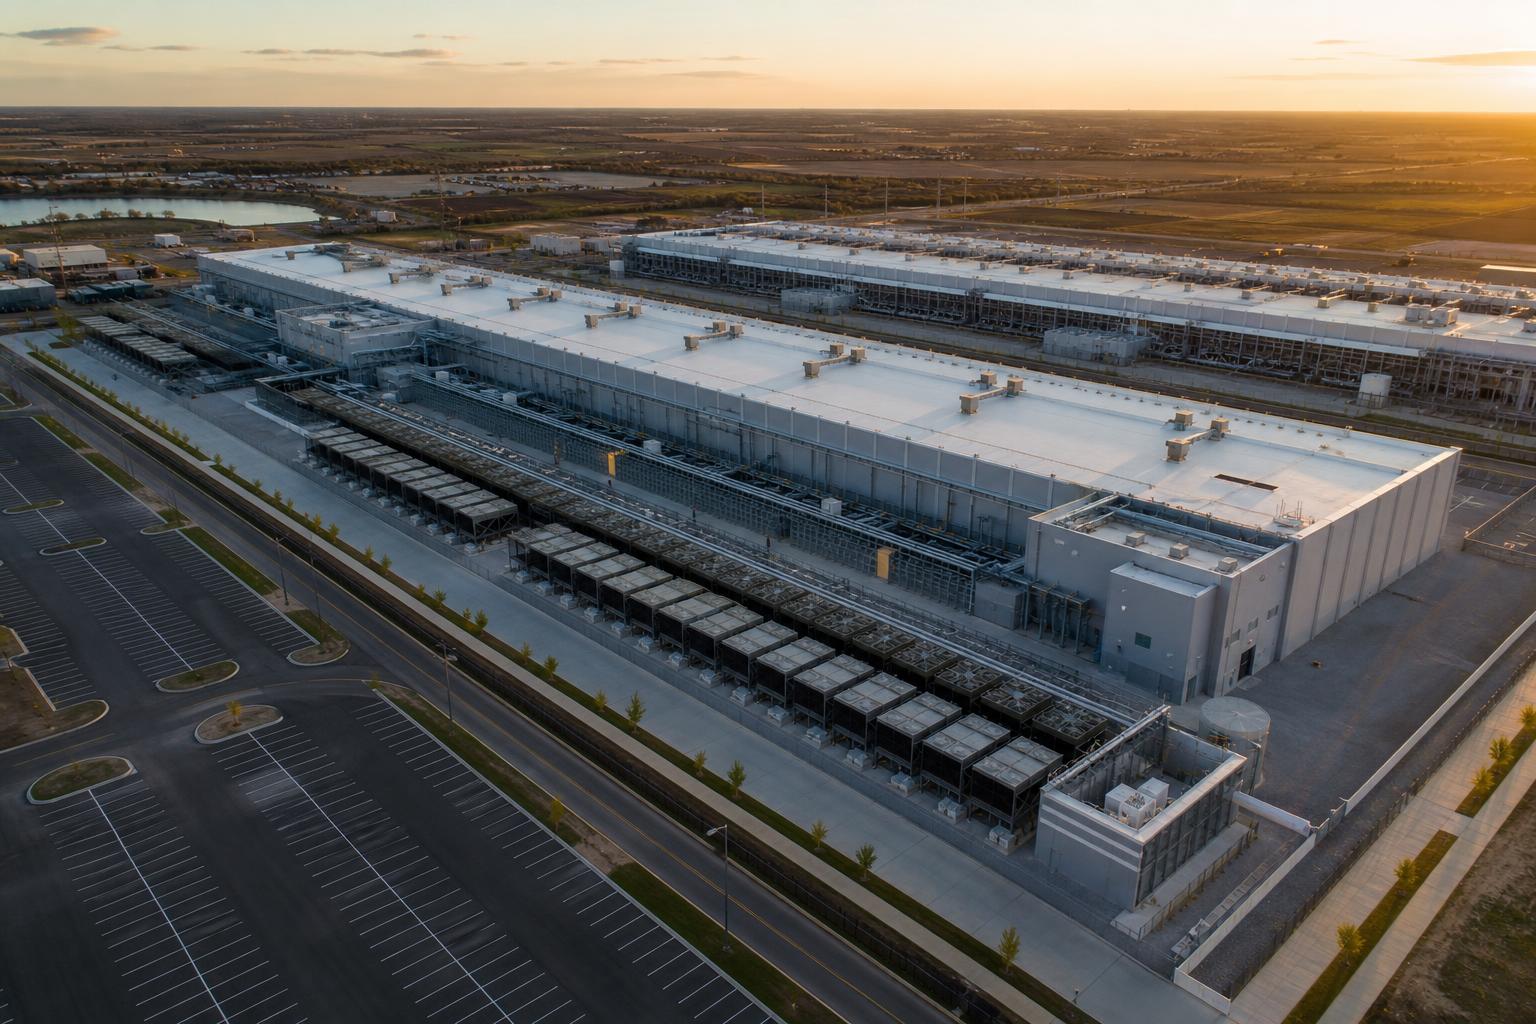
After the initial deployment of a cloud native application protection platform (CNAPP) like Wiz, Orca, or Palo Alto Networks Prisma Cloud, organizations typically face a predictable surge in visibility. For a mid-market enterprise with 1,000 to 5,000 employees, this often translates to a backlog of 5,000 to 15,000 findings across AWS, Azure, and GCP environments.
For the Cloud Security Lead (the influencer persona), this visibility creates an immediate operational deficit. The platform has succeeded in its primary function: detection. However, the existing cloud security team, often consisting of two to five engineers, now faces a backlog that exceeds their manual remediation capacity. Without a shift in operating model, the Mean Time to Remediate (MTTR) for critical findings frequently stretches beyond 120 days, often leading to audit failures or internal SLA breaches.
The triage paradox in the first 30 days
The first month post-rollout is defined by the triage paradox. While the CNAPP categorizes findings by severity (Critical, High, Medium, Low), these labels do not account for environmental context or the risk of breaking production. A "Critical" finding involving an open S3 bucket may be a known public data share, while a "Medium" finding regarding an overly permissive IAM role could be the primary vector for an active lateral movement path.
Security teams often attempt to resolve this by forwarding raw alerts to DevOps or engineering teams via Jira or Slack. This approach usually fails for three reasons. First, the lack of asset ownership metadata makes it difficult to route tickets to the correct service owner. Second, generic remediation guidance provided by the tool (e.g., "apply a more restrictive policy") lacks the specific infrastructure-as-code (IaC) syntax required for the customer's specific CI/CD pipeline. Third, developers, wary of breaking revenue-generating services, prioritize feature velocity over security tickets that lack a clear blast-radius assessment.
Operationalizing remediation between day 30 and 60
- 9.4
Remediation-as-a-service
- Works on top of your CNAPP
- Days
- Managed, human-supervised
- 7.6
CNAPP leader
- Broad, agentless
- Weeks to months
- Self-service platform
- 7.0
CNAPP
- Broad, agentless
- Weeks to months
- Self-service platform
- 6.6
CNAPP / CIEM
- Strong on entitlements
- Weeks to months
- Self-service platform
| Player | Coverage | Time to closed | Operating model | Score |
|---|---|---|---|---|
| LeaderRemediation-as-a-service | Works on top of your CNAPP | Days | Managed, human-supervised | 9.4 |
| CNAPP leader | Broad, agentless | Weeks to months | Self-service platform | 7.6 |
| CNAPP | Broad, agentless | Weeks to months | Self-service platform | 7.0 |
| CNAPP / CIEM | Strong on entitlements | Weeks to months | Self-service platform | 6.6 |
By the second month, the focus must shift from sorting the backlog to establishing a repeatable closure mechanism. Traditional CSPM and CNAPP tools are built for the security persona, providing dashboards that track the number of open issues. They are not built for the engineer who must execute the fix.
To move findings from "Open" to "Resolved," the workflow must integrate with the organization's existing change management process. This requires a three-step validation before any ticket reaches a developer:
- Contextual Enrichment: Determining if the resource is in production, staging, or a sandbox environment.
- Impact Analysis: Assessing whether changing a configuration (such as a Security Group rule or an IAM permission) will interrupt legitimate traffic or application calls.
- Remediation Scripting: Generating the exact Terraform, CloudFormation, or Pulumi code required to fix the issue in the source repository rather than the cloud console.
This is where the distinction between detection and remediation becomes most visible. While Wiz or Orca identify the risk, they do not own the lifecycle of the fix. Tamnoon addresses this gap by providing human-supervised remediation that integrates directly into the customer's change process. The model relies on Remediation Confidence Indicators (RCI) to categorize fixes as SAFE, RISKY, or AWAITING DATA. This reduces the friction between security and engineering by ensuring that only validated, low-risk fixes are promoted for implementation.
Overcoming the production paralysis objection
A common objection from VPs of Infrastructure is the fear of automated agents modifying live production environments. This fear is justified. Automated "auto-remediation" scripts that trigger on an alert frequently cause outages by missing edge cases in application logic.
The alternative is a supervised approach. By utilizing a read-only investigation layer, security teams can simulate the impact of a change before it is applied. This "Remediation-as-a-Service" model allows the organization to scale its remediation capacity without adding permanent headcount. Instead of hiring more cloud security engineers to manually investigate every Wiz alert, the team uses a platform that provides the investigation, the fix, and the verification of closure.
| Activity | Traditional CNAPP Operations | Remediation-as-a-Service (Tamnoon) |
|---|---|---|
| Finding Source | Platform Alert (Wiz, Orca, etc.) | Platform Alert + Blast Radius Analysis |
| Fix Generation | Generic Documentation Link | Environment-Specific IaC Templates |
| Verification | Periodic Rescan | Real-time closure tracking and guardrail application |
| Staffing | Requires 1-2 FTEs per 5,000 alerts | Human-in-the-loop expert support (CloudPros) |
Day 60 to 90: Measuring risk reduction
In the final third of the first 90 days, the metric for success shifts from "number of alerts seen" to "material risk reduction." For a CISO or VP of Security, this is often expressed as the percentage reduction in "Toxic Combinations" or critical attack paths.
Organizations that succeed in this phase move away from manual ticket handling. They implement guardrails that prevent the re-emergence of the most common misconfigurations. For example, if a team has successfully closed 200 overly permissive S3 buckets, the final step is not just closing the 201st, but implementing a Service Control Policy (SCP) or an Azure Policy that prevents the creation of public buckets by default.
This transition from reactive cleaning to proactive prevention is the primary goal of operationalizing a CNAPP. Success is not measured by the sophistication of the detection tool, but by the organization's ability to close findings faster than they are generated. By utilizing human-supervised remediation, teams can bridge the gap between the thousands of alerts surfaced by their CNAPP and the limited engineering hours available to fix them.
The bottleneck in cloud security is no longer the ability to find a hole in the fence; it is the capacity to patch it without bringing the fence down. Focusing on closure capacity, rather than detection volume, is the only path to a sustainable cloud security posture.
Advertisement
- For a mid-market enterprise with 1,000 to 5,000 employees, this often translates to a backlog of 5,000 to 15,000 findings across AWS, Azure, and GCP environments.
- While Wiz or Orca identify the risk, they do not own the lifecycle of the fix. Tamnoon addresses this gap by providing human-supervised remediation.
- Traditional CSPM and CNAPP tools are built for the security persona, providing dashboards that track the number of open issues.
- The platform has succeeded in its primary function: detection. However, the existing cloud security team, often consisting of two to five engineers, now faces a backlog that exceeds their manual remediation capacity.


